The Resiliency Capability
In the digital transaction space, system down-time is not a minor operational friction—it is a direct and permanent drain on revenue. In a highly competitive market like online sports betting, where service offerings are homogeneous and customer loyalty is thin, any platform interruption results in immediate transaction loss. If your platform is down during the final minutes of a major football match or the start of the Super Bowl, customers do not wait for your systems to recover; they simply switch to a competitor.
Traditional corporate strategies try to mitigate this risk by building massive quality-assurance gates, drafting hundreds of pages of technical specifications, and planning months of deployment lockouts.
However, this upfront defensive approach has a fundamental flaw:
“In addition to designing structure in supply chain processes and internal supply networks, it can be the case that effort can sometimes be less effective in trying to conceive and design out all possible eventualities upfront and that there will always be unknown unknowns when a system is in operation.”
In complex, highly concurrent systems, trying to prevent every failure by design is an impossible task. Real-world resilience is not about avoiding failures entirely; it is about building the capability to absorb, recover from, and adapt to them in real time.
1. The Perishable Transaction: Supply Chain Risk in Digital Services
In a physical supply chain, a logistics failure (e.g., a delayed shipping truck) typically results in back-orders or inventory delays. The transaction itself is delayed, but the revenue is often preserved.
In digital service supply networks, however, the product is entirely perishable, inseparable, and homogeneous (Christopher 2023; Slack & Brandon-Jones 2021).
- Perishability: A digital service transaction is consumed at the exact moment of demand. A sports bettor wants to place a wager on a live event now. If the platform cannot accept the transaction due to database lockouts or connection pool exhaustion, the opportunity is gone forever.
- Inseparability: The production of the service (odds processing, transaction ingestion) and its consumption (user placing the bet) happen simultaneously.
- Homogeneity: The core service offered by sportsbooks (odds on a specific match) is very similar. Because the customer’s switching barrier is practically zero, they will shop around for the best odds and most reliable platform.
Because of this, digital service networks are highly sensitive to operational risks. Minimizing recovery times and maintaining high availability are not just engineering metrics—they are core determinants of economic performance.
2. Dynamic Capabilities: Iterative Critical Incident Management
While traditional positioning strategy focuses on industry structure and market entry barriers (Porter 2004), the Resource-Based View (RBV) argues that a firm must possess resources and capabilities that are Valuable, Rare, Inimitable, and Organized (VRIO) to secure a sustainable competitive advantage (Grant & Jordan 2015; Wu 2023a).
In modern software organizations, resiliency cannot simply be bought or designed as a static asset. Instead, it must be developed as a dynamic capability—the ability to continuously integrate, build, and reconfigure internal competencies to address rapidly changing environments.
This dynamic capability is built through Iterative Critical Incident Management. Rather than treating incident response as a blame-oriented firefighting exercise, high-performing teams organize it as a continuous feedback loop:
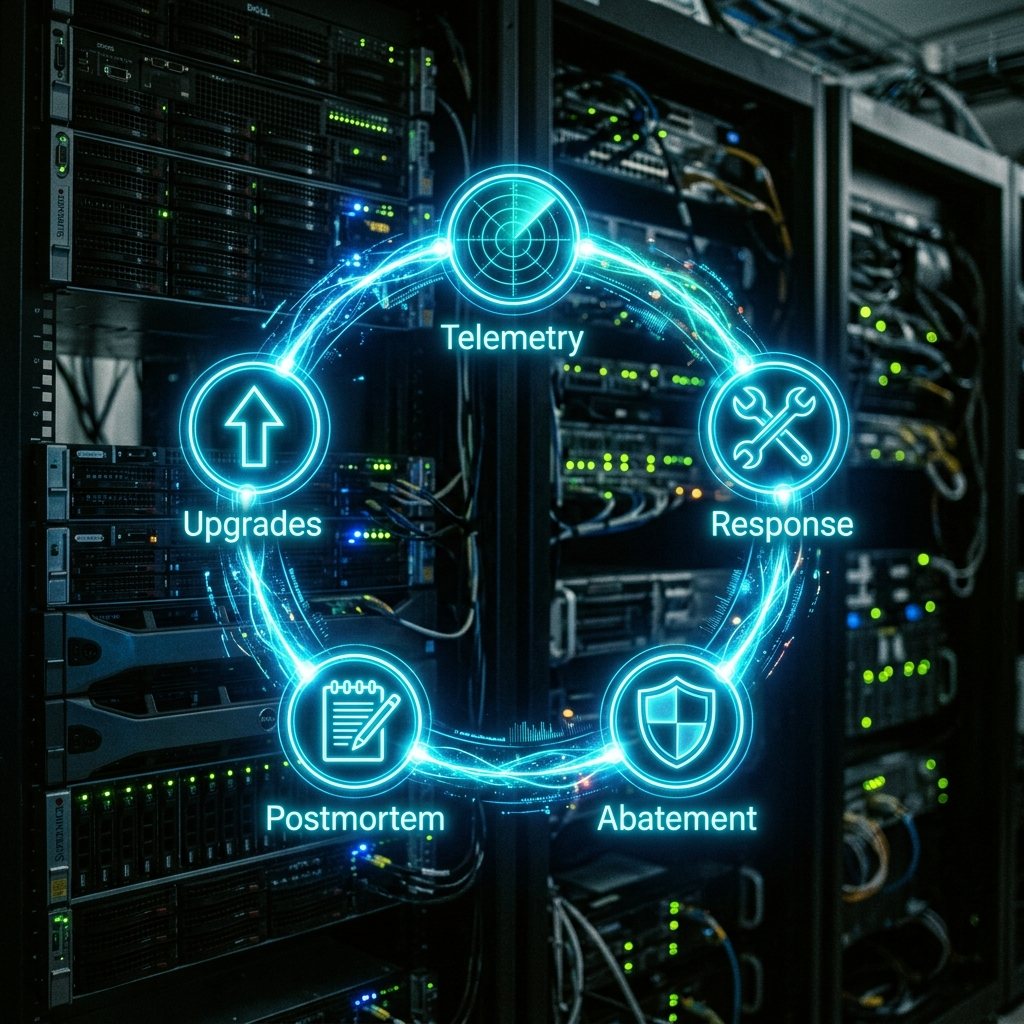
- Telemetry Trigger: Real-time instrumentation monitors system behavior and alerts the team before critical thresholds are breached.
- DevOps Alignment: The engineers who write the code are the same ones who operate it and respond to alerts (DevOps). This ensures deep system context during an active failure. This cross-functional alignment of development and operations roles builds strategic human capability, reducing communication overhead during critical incidents (Bailey et al. 2018).
- Immediate Abatement: Responders isolate failing services or switch traffic pathways to restore availability as quickly as possible.
- Post Incident Analysis (PIA): Following resolution, a blameless retrospective is held. The team documents the timeline, walks through every diagnostic step, and reviews what documentation or telemetry was missing or misleading.
- Proactive Backlog Upgrades: Systemic causes are fed back into the sprint backlog—updating runbooks, refactoring brittle code paths, and introducing new telemetry rules.
“Unlike one off upfront process design the deliberate, regular and sustained improvement in risk performance is effective in responding to the dynamics of a constantly changing environment.”
By continually feeding the lessons of actual failures back into the development process, the organization iteratively builds a resilient operational structure that competitors cannot easily copy.
3. Sharding Risk: The Blue-Green Deployment Strategy
In high-concurrency environments, a primary source of operational risk is the deployment of new features and system enhancements. As system complexity increases, deployments become slower, quality-control failures slip into production, and unpicking bad changes becomes extremely difficult under load.
To mitigate this risk, resilient organizations deploy a structural pattern called Blue-Green Deployments:
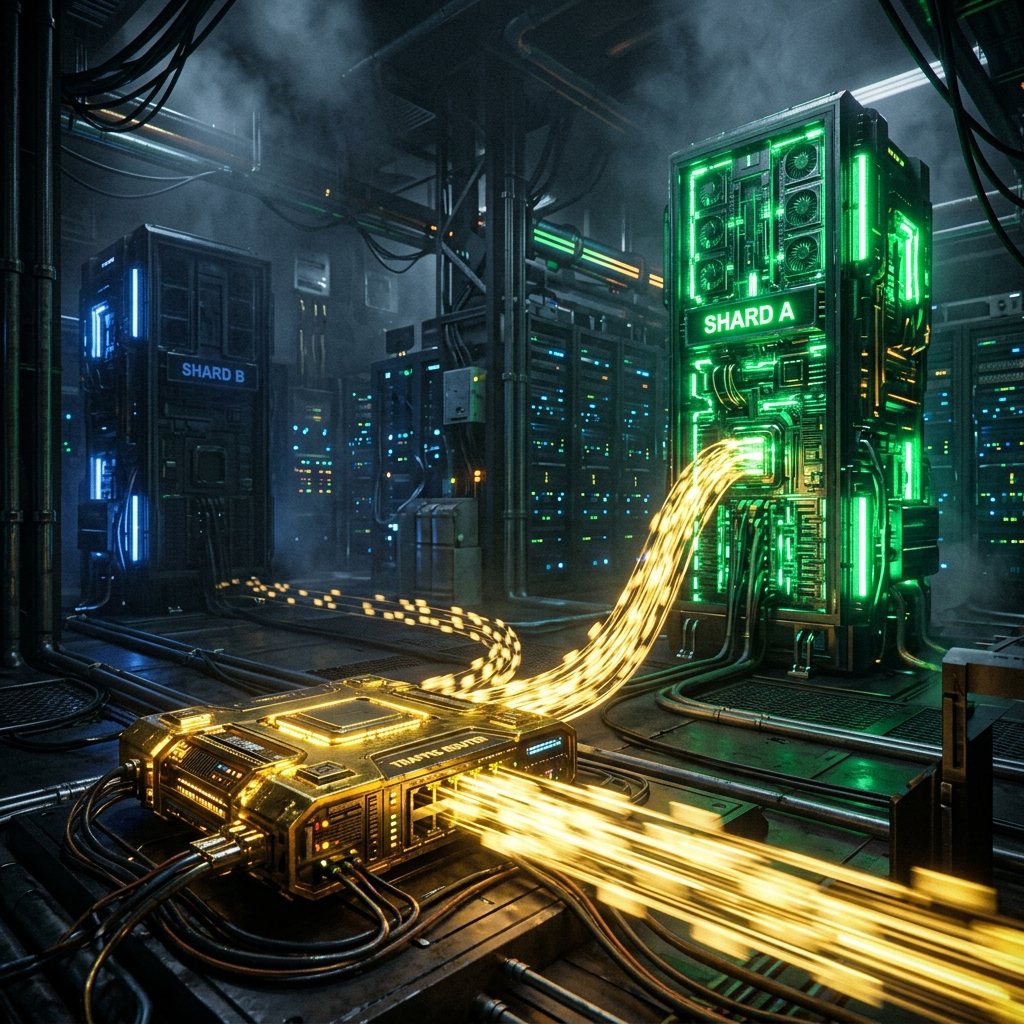
In a Blue-Green deployment architecture:
- The system is split into two identical production shards: Blue and Green.
- Only one shard (e.g., Green) receives live user traffic.
- The new release is deployed to the inactive shard (Blue), where it can be fully tested under real-world conditions without affecting live users.
- Once verified, the traffic router swaps the destination, directing live users to the Blue shard instantly.
This architecture decouples system availability from deployment risk. If a subtle quality issue is discovered post-release, the operator does not need to rush out a hotfix or unpick a complex merge under pressure. They simply toggle the router back to the inactive shard, restoring the last-known good state in seconds.
By sharding the environment, you decouple the time taken to restore system availability from the time taken to identify and resolve the underlying code failure.
4. Telemetry and Fatigue: Designing the Alert API
A critical challenge in building a resilient DevOps capability is managing alert noise. If system warnings are too sensitive, responders develop alert fatigue, ignoring warning indicators until a catastrophic failure occurs.
To manage this operational risk:
- Actionable Alerts: Alerts must only trigger when an immediate human intervention is required to prevent a system failure. If an event is transient or self-healing, it should not page an engineer.
- Telemetry Dashboards vs. Alerts: Where system telemetry exhibits high natural variance (e.g., transaction volume fluctuation during live sporting matches), binary threshold alerts are ineffective. Instead, teams should design active inspection dashboards that map trends, allowing engineers to spot anomalies through visual pattern recognition during high-volume periods.
Resilience is not a project with a start and end date; it is an ongoing capability built through continuous improvement, blameless reflection, and decoupled system architecture.
Conclusion: Preserving the Perishable Transaction
When the final minutes of a major football match are ticking away, or the Super Bowl kick-off is seconds away, your users are not thinking about your architectural diagrams or your release gates. They are thinking about placing their bet. If your systems fail, they switch to a competitor, and that transaction revenue is lost forever.
By building The Resiliency Capability—shifting from the illusion of static, upfront defensive design to a dynamic, iterative cycle of continuous improvement—organizations accept the reality of “unknown unknowns.” By decoupling deployments via Blue-Green sharding, designing alert systems that prevent cognitive fatigue, and treating every production incident as a source of system improvement, we do not just build more reliable software. We protect the core economic engine of the business, ensuring that when the critical moments arrive, our platforms are ready to capture the transaction.
References
- Bailey, C., Mankin, D., Kelliher, C. and Garavan, T. (2018) Strategic Human Resource Management. New York: Oxford University Press.
- Christopher, M. (2023) Logistics and Supply Chain Management. 6th ed. Harrow, England: Pearson.
- Grant, R. M. and Jordan, J. J. (2015) Foundations of Strategy. 2nd ed. Chichester: Wiley.
- Porter, M. E. (2004) Competitive Strategy: Techniques for Analyzing Industries and Competitors. Export ed. New York: Free Press.
- Slack, N. and Brandon-Jones, A. (2021) Operations and Process Management. 6th ed. Harrow, England: Pearson.
- Wu, J. (2023a) BU5048 Business Strategy. Lecture Notes, University of Aberdeen (26th September 2023).